Most skepticism about AI inside the ledger is really skepticism about plumbing. The question is not whether an agent can draft a journal entry or match a receipt. The question is which identity it holds while doing so, which systems that identity can reach, how long its credentials live, what it is allowed to see, and whether an auditor can reconstruct the sequence six months later. Those are infrastructure decisions, not model decisions. They are the primitives a controller should insist on before any agent touches ERP, CRM or bank rails.
The industry now has a shared vocabulary for getting this wrong. OWASP published its first Top 10 for Agentic Applications in December 2025, and three of its top four risks are identity, tool and delegation failures rather than model failures. This piece is the construction manual that sits under those risks: what to build, what to refuse, and what to demand from any vendor claiming to run finance workflows for you. It is a companion to the earlier posts on what an agent structurally cannot do inside a ledger and on AP approval thresholds. Both of those assume the plumbing described below is already in place.
Give Every Agent Its Own Identity
The first failure mode is shared credentials. An agent running under the deploying engineer's personal access token inherits that engineer's rights across every connected system, which means a prompt injection or a confused tool call is executed with full human privileges. Docker's guidance for development teams puts the rule plainly: provision agents with dedicated, scoped credentials that carry only the permissions the task requires, and treat the agent as a first-class identity in the access management system.
Per-agent identity is not per-agent-type. It is per instance, per session, bound to the specific task. NIST SP 800-207A is explicit that each service should present a short-lived, cryptographically verifiable identity credential that is reauthenticated per connection. A long-lived token with admin scope that happens to rotate every ninety days does not satisfy this. The AR agent reconciling cash should hold a different identity from the AR agent that drafts customer statements, and both should be distinguishable in the audit log from the human controller who delegated the work.
A workable test for any vendor pitch: ask to see the IAM record for one agent. If what comes back is a service account named something like erp-integration-prod, the architecture is one generation old.
Scope Credentials to the Task, Not the Role
The second failure mode is standing access. A credential that lives forever, even a narrowly scoped one, is a credential waiting to be exfiltrated. The direction of travel is least-privilege per task rather than per agent type, with short-lived tokens issued at the start of a workflow and expired at its end. Aembit's write-up on agentic access frames it as separately scoped, short-lived credentials issued for the specific operation, with every step logged against both the agent identity and the human context that initiated it.
In an ERP setting this means the AP agent's token for a given invoice run can read vendor master, read open POs, and post to a holding account. It cannot approve above threshold, modify vendor banking, or touch payroll. When the run ends, the token is gone. If the same agent is asked ninety seconds later to answer a controller's question about an aged payable, it draws a new token with a narrower read scope and no write capability at all.
This is what least-agency looks like in practice. The OWASP framework names least agency as the architectural principle behind the whole Top 10: grant only the minimum autonomy required for a bounded task. Finance teams who have lived through SOX walkthroughs will recognise this as segregation of duties, restated for non-human actors.
Keep Secrets Out of the Model Context
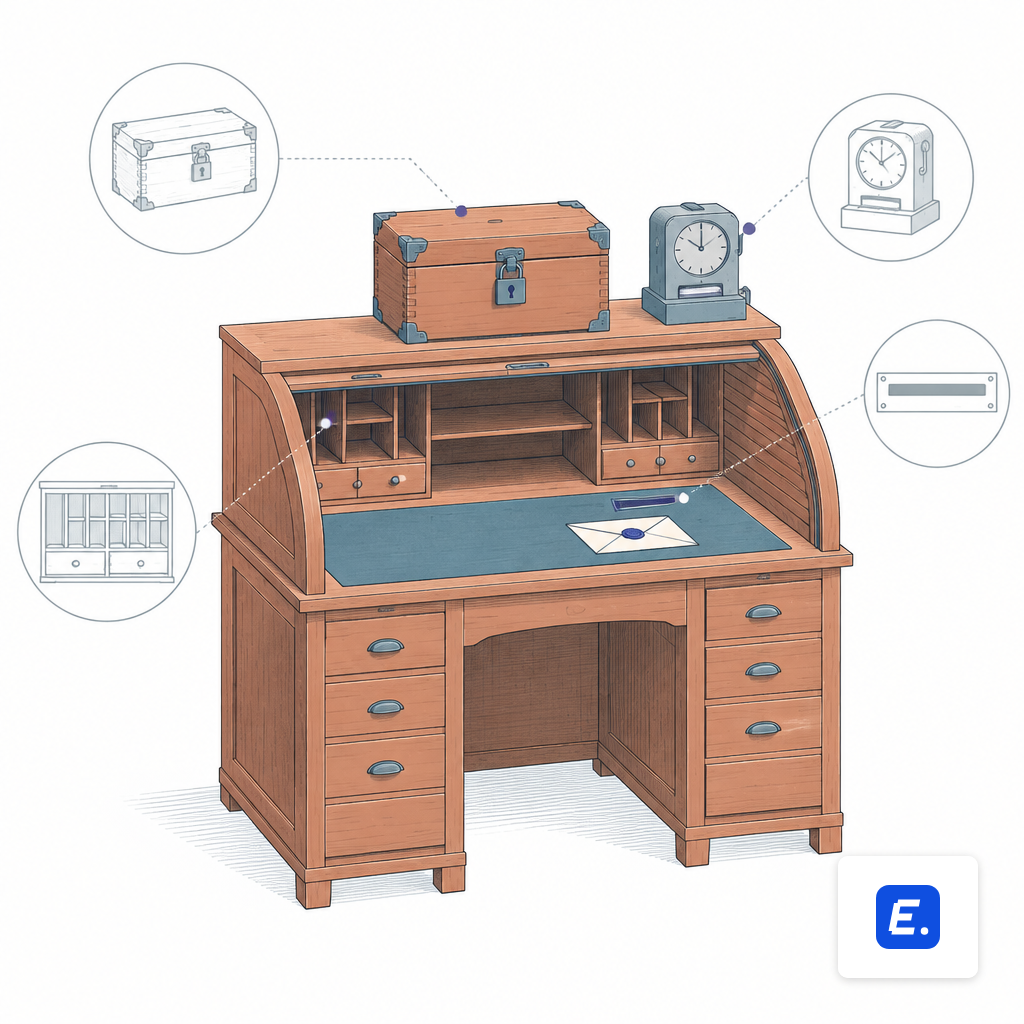
A context window is not a vault. Secrets passed through prompts can be logged, replayed in traces, surfaced in error messages, or extracted by a crafted retrieval. The point is structural rather than configurational: credentials belong in a token service that issues them at task time and never persist in the model's context. A corollary is that any system prompt containing a bearer token or an API key should fail code review on sight.
The pattern that holds up is a token exchange. The human signs in to the identity provider. A tool server receives the user's token, exchanges it for a short-lived credential whose audience is the ERP API and whose scope is narrower than the user's own entitlements, and only that exchanged credential ever reaches the system of record. The model sees a tool handle, not a secret. Credential rotation is handled by the exchange itself; nothing is cached in agent memory.
This also forces a decision about delegation that most teams skip. When the CFO agent summarises receivables for a board pack, is it acting as the CFO, as a service account, or as both? The honest answer is both, and the audit log needs both principals recorded on every call. Legacy ERPs that identify callers only by API key cannot support this and will quietly collapse the two identities into one.
Treat Retrieved Content as Untrusted
Indirect prompt injection is the risk category finance teams underestimate most. A vendor email, a PDF invoice, a CRM note, a comment field on a bank statement, a line in a supplier portal: anything the agent reads is a potential instruction channel. Research on retrieval poisoning has shown that as few as five crafted malicious documents in a corpus can steer a RAG system toward attacker-specified outputs with roughly 90% success. The agent does not need to be jailbroken. It needs to be read a convincing-sounding instruction inside a document it was asked to summarise.
The defences are architectural rather than prompt-level. Separate instructions from data at the API boundary rather than concatenating them as strings. Pin the set of tools and MCP servers an agent may reach rather than permitting dynamic discovery. Require human confirmation for any action that moves money, changes a vendor bank account, or writes to the ledger. Obsidian's guidance on prompt injection is blunt about the implication: an attacker who can write to the wiki can write to the agent's context, so internal sources deserve the same scepticism as external ones.
For a finance platform, this is also why the ledger itself should be deterministic and off-limits to the model. The agent proposes a journal entry. The ledger engine validates balance, period, dimension and approval state, and either posts or rejects. The model never writes directly. Prompt injection then has nowhere useful to land, because the only way into the ledger is through the same validator a human would use.
Log Enough to Reconstruct the Decision
Audit trails for human users record who, what and when. Audit trails for agents need more. The minimum useful record covers the acting agent identity and version, the parent human or system that authorised it, the tools called with their arguments, the data retrieved, the decision taken, the policy that permitted it, and the before and after state of anything changed. Field schemas for agent audit events typically treat the parent identity as the anchor of the chain of responsibility, because without it the log cannot answer the only question the auditor really has: on whose authority did this happen.
Two further requirements separate serious implementations from theatre. The log store must be tamper-evident, which usually means append-only with cryptographic chaining, because the agent itself must not be able to rewrite its own history. And the schema must survive model upgrades: an entry written by last quarter's agent needs to remain legible to this quarter's auditor without a migration. Teams building toward the NIST AI Risk Management Framework and SOX in parallel find that non-repudiation and audit-trail integrity are the gaps regulators call out most often.
Build a Gateway, Not a Honor System
The last primitive ties the rest together. Rather than letting each agent call each system directly, route every tool invocation through a policy enforcement point: a gateway that authenticates the agent, checks the scope on the token, applies the organisation's rules, logs the attempt and the decision, and only then forwards the call. A gateway is where threshold logic lives, where kill-switches terminate a run, where behavioural monitoring flags a tool-call sequence that looks nothing like last week's baseline, and where the auditor finds a single pane of evidence rather than a dozen scattered logs.
Controllers evaluating platforms, including AI in ERP as it is implemented here, should walk the gateway in a demo. Ask what happens when an agent requests an action its scope does not permit. Ask to see the denial logged. Ask how an administrator revokes a running agent's credentials mid-task. Ask where behavioural baselines are stored and how drift is alerted. The same questions belong in any RFP scoring exercise and in the acceptance criteria for a two-week pilot.
What the Checklist Looks Like
Finance-systems leaders do not need another philosophical defence of agents. They need a short list to challenge any build, internal or vendor-supplied:
- Every agent has a unique identity registered in IAM with a named human owner.
- Credentials are short-lived, scoped to the task, and issued by a token service that the model cannot read.
- User context is preserved through delegation; no token is replayed down the chain.
- Retrieved content is treated as untrusted; tool sets and MCP servers are pinned.
- Irreversible actions require explicit human confirmation above policy thresholds.
- Every tool call is logged with agent, parent, scope, decision and before/after state in an append-only store.
- All calls traverse a gateway that enforces policy and can suspend an agent in flight.
None of this is exotic. It is the identity, scoping, secrets, retrieval and logging discipline that enterprise security teams have been building toward for years, applied to a new class of principal. The agents that will earn a seat inside the ledger are the ones built on this plumbing from day one. For teams weighing whether to construct it themselves or inherit it, the platform documentation and a free assessment are the places to start the comparison.